Paper · 2025
Principles for Initialization and Architecture Selection in Graph Neural Networks with ReLU Activations
Deep graph neural networks often fail before training even starts. This paper identifies three ways that happens at initialization — outputs that explode or vanish with depth, oversmoothing, and correlation collapse — and derives the initialization and residual-architecture choices that avoid each one, keeping GNNs trainable at large depth.
- A graph-aware version of He initialization for ReLU GNNs keeps the forward and backward passes stable.
- Oversmoothing is shown to set in exponentially with depth for a fixed message-passing operator, whatever the initialization.
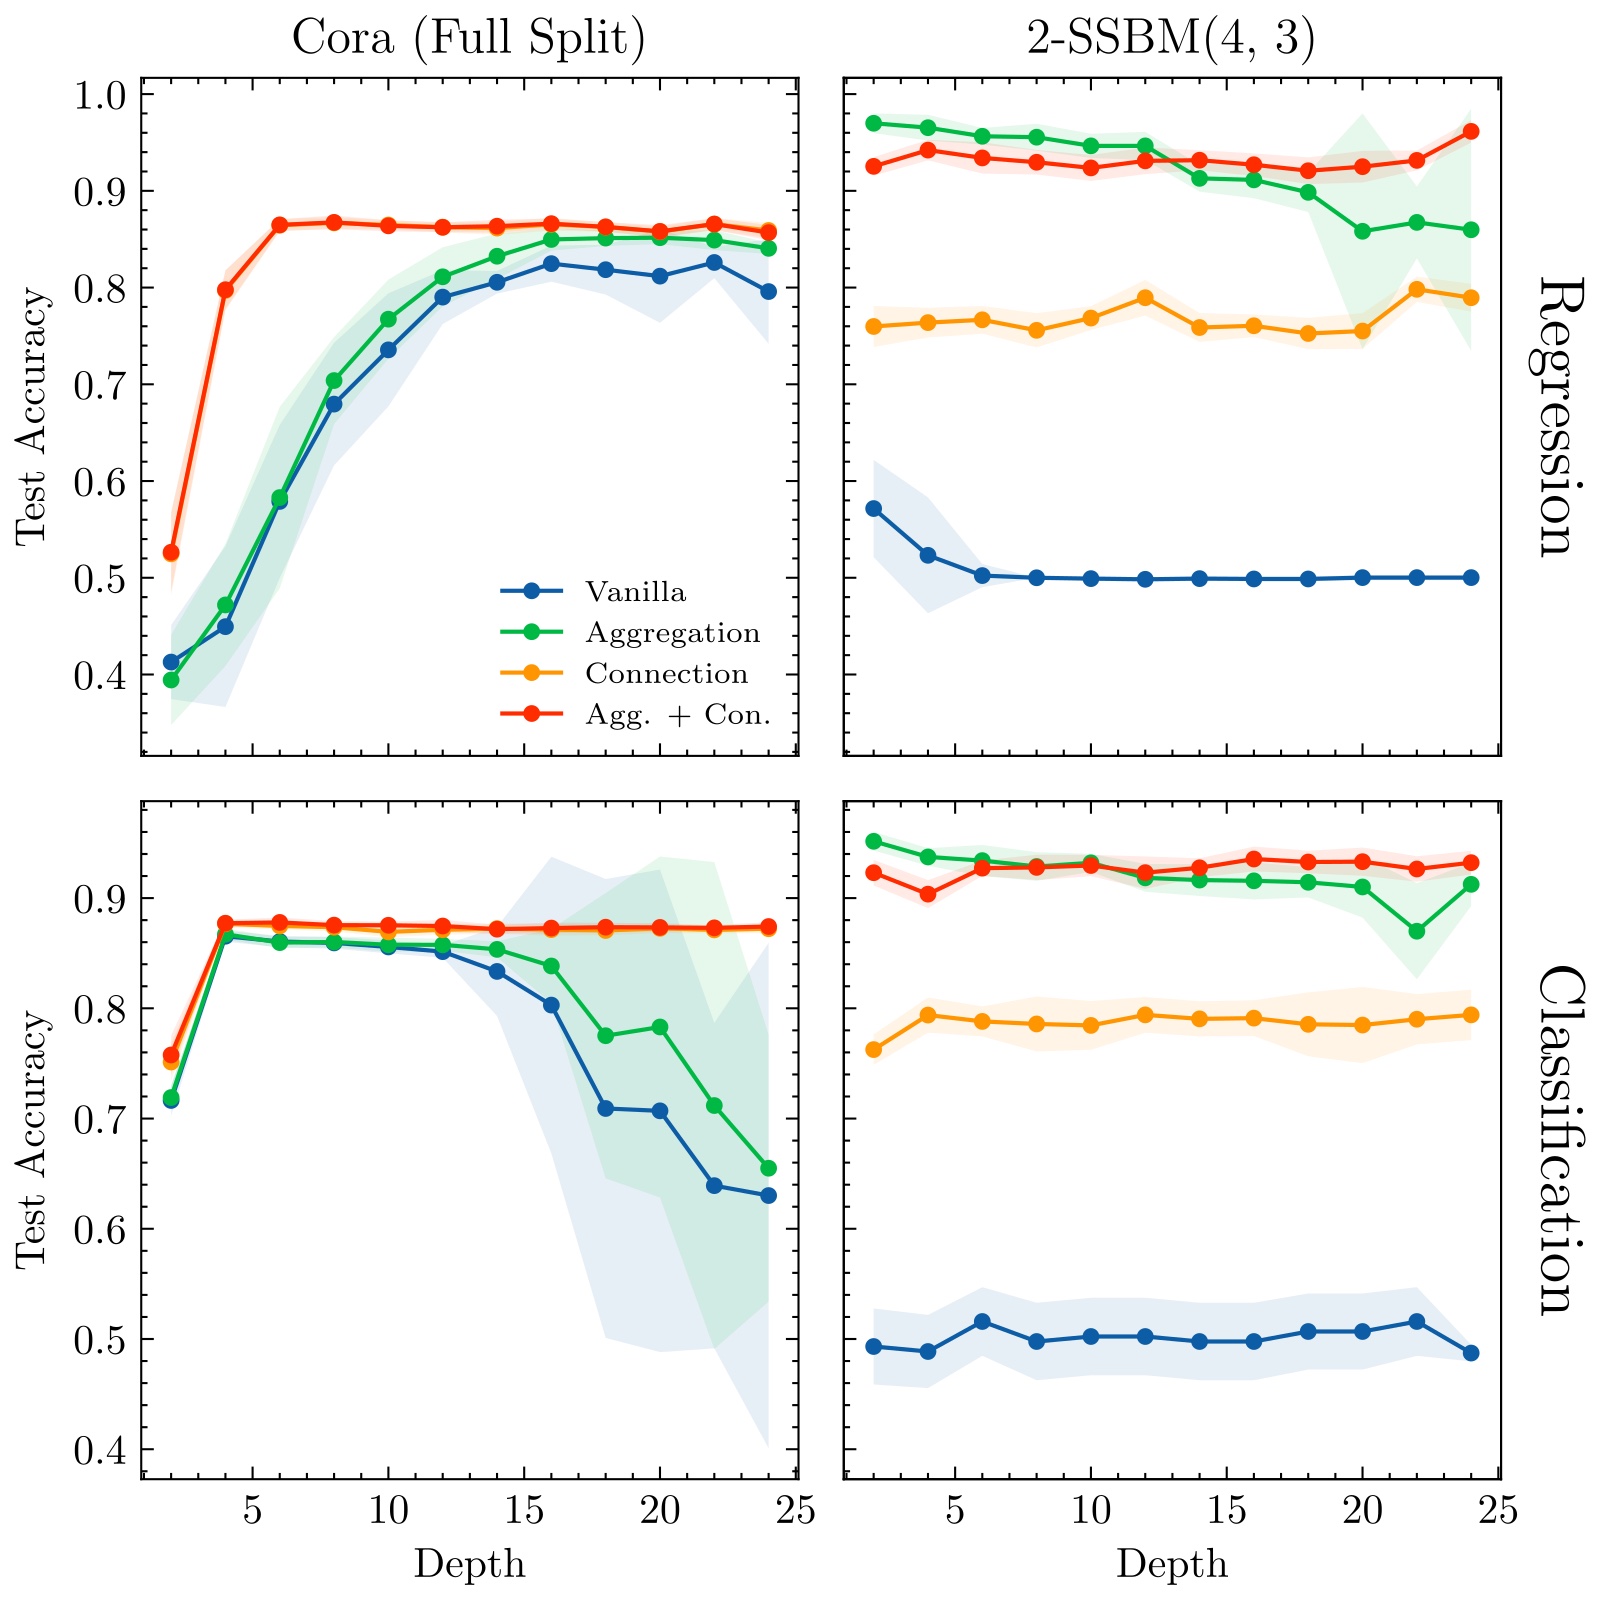
- Residual aggregation and residual connections control oversmoothing and correlation collapse, and improve time-to-train.