Paper · 2026
Hyperparameter Transfer in Graph Neural Networks
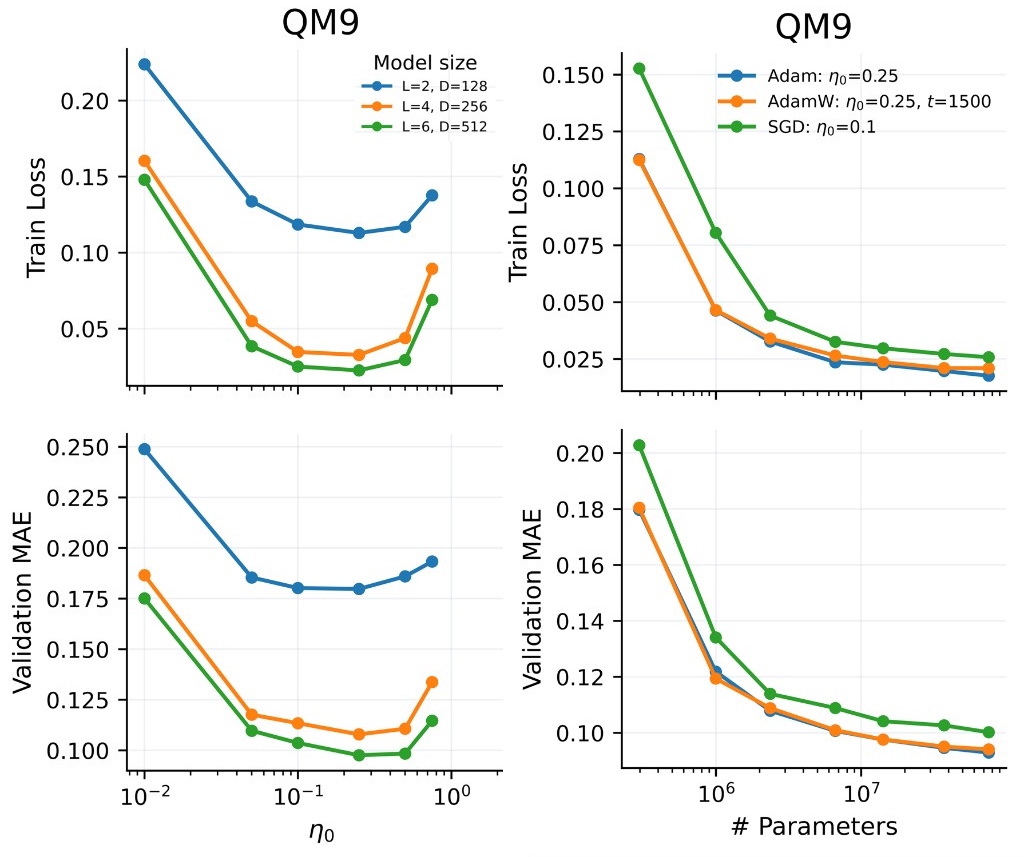
Good hyperparameters usually shift as a model grows, which makes large graph neural networks expensive to tune. This paper gives a parameterization under which the learning rate, initialization scale, and weight decay stay put as width and depth increase, so you can tune a small model once and reuse its settings on a much larger one.
- Covers training with SGD, Adam, and AdamW, with performance improving as models get wider and deeper.
- For SGD, a graph-dependent correction to the first layer speeds up early training on sparse bag-of-words inputs.
- For Adam, how message passing is normalized decides whether settings transfer; one extra hyperparameter controls it.
- For AdamW, learning rate and weight decay transfer together.